
Build data pipelines you can see.
An open source platform for data integration and orchestration. Design pipelines and workflows on a canvas, then run them where they belong — locally, on a remote Hop Server, natively on Apache Spark, or on Flink and Dataflow through Apache Beam.
docker run -p 8080:8080 apache/hop-web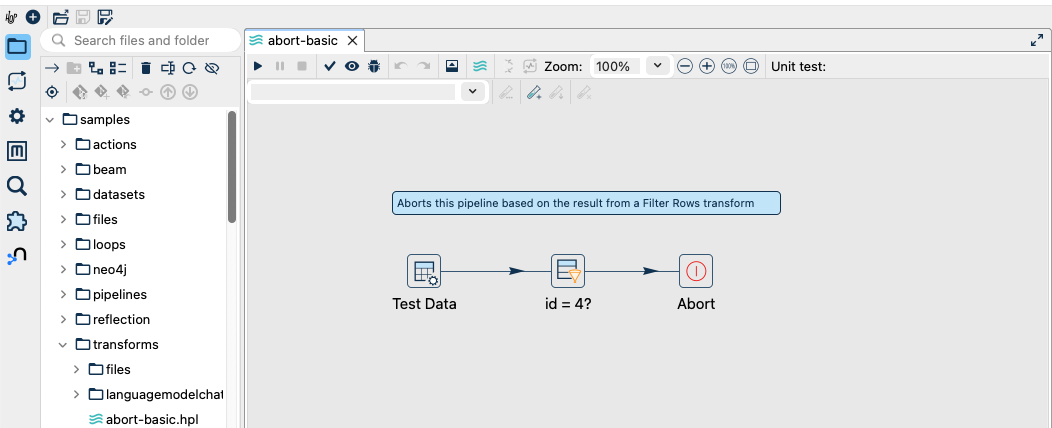
Design, run, manage
Three things Hop does that a scheduler plus a pile of scripts does not.
Design
On a canvas, not in a config file
Drag transforms onto a pipeline and join them with hops. Preview rows at any step, sniff live data while it runs, and see metrics on the canvas itself. Nothing is generated and nothing is compiled.
Run
Anywhere, without a rewrite
The same pipeline runs on the native engine locally, on a remote Hop Server, or on Spark, Flink and Dataflow through Apache Beam. The runtime is a run configuration, not a different codebase.
Manage
Projects and environments, not copies
Configuration lives beside the work rather than inside it. Move a project from development to production by switching environment, and keep credentials out of the pipelines entirely.
Run it where your data already is
The engine is a run configuration, not a rewrite. Point the same pipeline at a different runtime and the pipeline itself does not change.
- Localnative
- Hop Servernative
- Apache Sparknative
- Databricksnative
- Apache SparkBeam
- Apache FlinkBeam
- Google DataflowBeam
What's in the box
Transforms, workflow actions and database dialects ship with the platform. The marketplace adds the rest.
- 250+pipeline transforms
- 80+workflow actions
- 40+database dialects
Including, out of the box:
- PostgreSQL
- MySQL
- Oracle
- SQL Server
- Snowflake
- BigQuery
- Redshift
- Databricks
- MongoDB
- Neo4j
- Kafka
- Cassandra
- Salesforce
- SAP
- Parquet
- Avro
- S3
- Azure Blob
- Google Cloud Storage
- REST
- SFTP
Latest from the blog
Built by a community, at the Apache Software Foundation
Hop is developed in the open under the Apache License 2.0. Everything happens on the mailing lists and in the issue tracker, and new contributors are genuinely welcome.